
A fingerprint matcher can return a high similarity score and still point to the wrong person. The print may have been captured poorly, the wrong fingers enrolled, or the database may contain near-duplicate records. During the 2000s, biometric researchers increasingly treated these conditions as part of the technical problem, not as nuisances outside the algorithm. The decade’s impact came less from one breakthrough than from advances in capture, measurement, evaluation, and large-scale operation.
Biometrics uses measurable human characteristics to support recognition. Fingerprints, faces, irises, voices, and hand geometry were all deployed or actively studied during the period. The task matters as much as the trait: verification checks a sample against a claimed identity, while identification searches enrolled records for a person. A search across millions of records creates different error pressures from a check at a single terminal. That distinction shaped research papers and procurement decisions throughout the decade.
Why the 2000s changed the scale of the problem
Biometric identification was not new in 2000. Automated fingerprint identification systems had developed over preceding decades, and face and voice recognition had established research communities. Cheaper digital sensors, more capable computing, networked databases, and demand for identity checks in civil and border settings changed the scale. Researchers could test methods on larger collections; agencies had to manage enrollment queues, uneven capture conditions, and searches against growing repositories.
That growth made one-to-many search especially consequential. Even a small chance of a misleadingly high score in each comparison creates more opportunities for false leads when many records are searched. A system may therefore return a ranked candidate list for human review rather than declare a certain identity. In one-to-one verification, a threshold might instead determine whether a traveler’s live sample sufficiently resembles the biometric associated with a presented credential. Neither result establishes, on its own, that the document was legitimately issued or that its holder is authorized to enter.
Standards work grew more important as enrollment and matching crossed organizational boundaries. ISO/IEC biometric standards developed common approaches to data interchange, performance testing, and reporting. A shared image format could help organizations exchange a fingerprint or face record, but it could not guarantee identical match scores. Sensor quality, compression, template extraction, and the makeup of the enrolled population still mattered.
From a physical trait to a searchable record
A biometric transaction involves more than a camera or scanner observing a person. The system must acquire a sample, assess its quality, turn it into a representation, and compare it with stored records. Trouble at one stage may show up later as a recognition error. That is why research on acquisition and image quality mattered alongside work on classifiers.
Capture quality became a measurable variable
Fingerprint readers faced dry or worn skin, partial contact, distortion from finger pressure, and residue on the platen. Face systems contended with pose, illumination, expression, resolution, and changes in appearance over time. Iris capture needed enough detail while managing eyelids, reflections, focus, and the subject’s position. Speech-based systems had to account for microphones, channel noise, speaking style, and short utterances. These sources of error were not interchangeable: a low-resolution face and a smudged fingerprint called for different quality checks and remedies.
Researchers increasingly asked whether a new sample was usable before treating its match score as meaningful. Fingerprint image-quality measures, for example, could flag prints unlikely to support reliable minutiae extraction. A system might request another capture, use a different enrolled finger, or send the case for review. Recapture takes time, though, and may not solve a persistent accessibility or sensor problem. Quality control connected laboratory accuracy to what people experienced during enrollment.
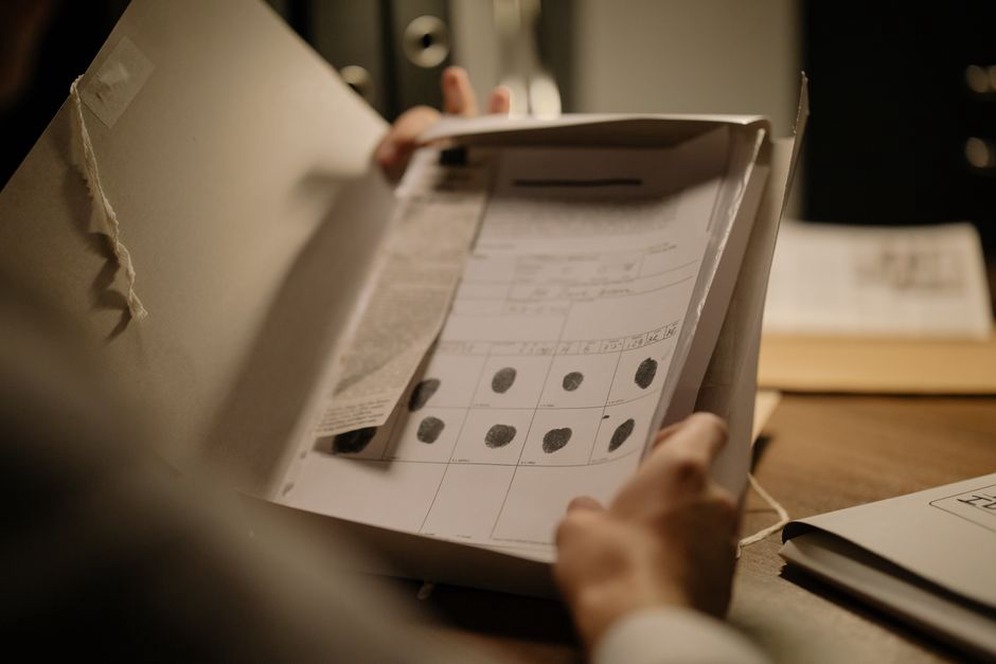
Templates simplified matching but did not erase risk
Matching systems commonly stored a derived representation, often called a template, rather than relying solely on a raw image. A fingerprint template might encode the locations and orientations of ridge endings and bifurcations, known as minutiae. An iris system could encode texture after locating and normalizing the iris region. Face methods used several representations, including measurements derived from facial images and learned statistical features.
A template reduces a complicated sample to features suited to comparison. It is not an anonymous or universally safe version of the original. Templates can remain sensitive personal data, and their usefulness depends on the capture and processing methods behind them. They were not necessarily compatible across vendors, either. In the 2000s, interoperability required agreed data formats and testing of what happened when different devices and algorithms handled records from the same people.
Where innovation appeared across modalities
No single biometric was best for every job. Each presented a different balance of capture effort, search performance, environmental sensitivity, and suitability for a given setting.
- Fingerprints: Established identification workflows benefited from digital capture and faster search. Latent prints recovered from surfaces remained especially difficult because they could be partial, distorted, or contaminated.
- Faces: Cameras allowed relatively unobtrusive capture and made comparison with identity photographs attractive, but pose and lighting could substantially alter performance.
- Irises: Detailed iris texture supported strong recognition under suitable capture conditions, though consistently focused images placed demands on sensors and users.
- Voices: Speaker recognition could use existing audio channels, making it appealing for telephone interactions. Channel differences, illness, and changes in speaking behavior complicated comparisons.
Face recognition shows how algorithmic work and evaluation developed together. The Face Recognition Vendor Test 2002 and Face Recognition Vendor Test 2006 assessed systems under specified conditions and helped document progress. They did not show that face recognition worked equally well on every camera, population, or task. They did let researchers compare submitted systems on common data and examine factors such as image quality. Work on features less sensitive to variation and on three-dimensional facial information addressed some difficulties without resolving them all.
A well-captured iris can contain highly distinctive texture, which helped draw attention to iris recognition. But distance, focus, and subject cooperation could make operational results quite different from matcher results on clean images. A telephone speaker verifier might likewise perform well on recordings made through similar channels yet struggle when enrollment and later calls used different devices. Claims that one modality was categorically superior seldom answered the deployment question.
Multimodal systems offered another approach: combine face and fingerprint evidence, for example, or use multiple fingers. Combining evidence could reduce dependence on one weak sample and provide an option when one modality could not be captured. It also raised questions about score combination, missing samples, and the extra burden of capture. Two sensors did not automatically make a system fairer or more accurate; researchers had to measure their errors and the effects of combining them.
Benchmarks, thresholds, and what a score meant
As testing matured, shared protocols and measures helped researchers distinguish kinds of failure. Failure to enroll means an initial usable record cannot be obtained. Failure to acquire can occur when a later attempt yields no usable sample. A false-match rate calculated only on successful comparisons describes neither problem. Excluding difficult captures can make a matcher look better while hiding a system that repeatedly turns people away.
For verification, the false match rate measures how often samples from different people are incorrectly accepted as matching. The false non-match rate measures how often samples from the same person are incorrectly rejected. Both depend on the decision threshold and test population. Lowering a threshold may admit more legitimate users, but it can also admit more impostor attempts. An equal error rate marks where the two rates meet under a paper’s test conditions; it is not a ready-made threshold for a border crossing or hospital workstation.
Identification evaluations need other distinctions. Does the correct identity appear first in a ranked list, somewhere in a short candidate list, or above a threshold? Can the person be absent from the database? That last situation, called open-set identification, is harder than a search in which the subject is known to be enrolled. Database size, demographic composition, and probe quality all affect the meaning of a reported result. A small, tidy academic collection can reveal an algorithmic improvement without predicting performance in a busy enrollment program.
For a related distinction between match scores, identity claims, and security decisions, the blog’s retrospective on mid-2000s biometric security examines what a successful comparison could actually prove. Recognition evidence is one part of an identity process, not a substitute for the rest of it.
Deployment exposed the limits of laboratory success
Large programs faced questions a matcher benchmark could not answer. Enrollment required linking a person’s record to an identity established through other procedures. Operators needed ways to handle duplicate records, poor-quality samples, equipment failure, and people whose characteristics were difficult to capture. A false non-match could delay someone despite impressive average accuracy. A false match in a search could produce an investigative lead that needed independent checking.
Differences across groups became an important evaluation concern. Skin conditions and occupational wear could affect fingerprints; lighting and camera exposure could interact with facial appearance; age and other factors could affect capture or matching. One aggregate error rate could conceal unequal experiences. Historical studies did not always have enough demographic detail or enough participants to measure every disparity reliably. The careful course was to state who was tested and under what conditions, rather than generalize beyond them.
Presentation attacks also limited claims based solely on matching accuracy. A comparison engine judges the sample it receives; matching alone cannot establish that it came from a live, willing person at the sensor. Researchers investigated liveness and presentation-attack detection, while operators considered supervision, device design, and procedural checks. Each addressed a different part of the problem and needed assessment without publishing instructions for defeating the system.
Privacy raised a further design question. Biometric traits are closely linked to a person and generally cannot be replaced like a password, so databases carried lasting responsibilities for access control, retention, audits, and correction of mistaken records. Convenient capture did not make widespread collection harmless. The ability to exchange a record was separate from permission to reuse it.
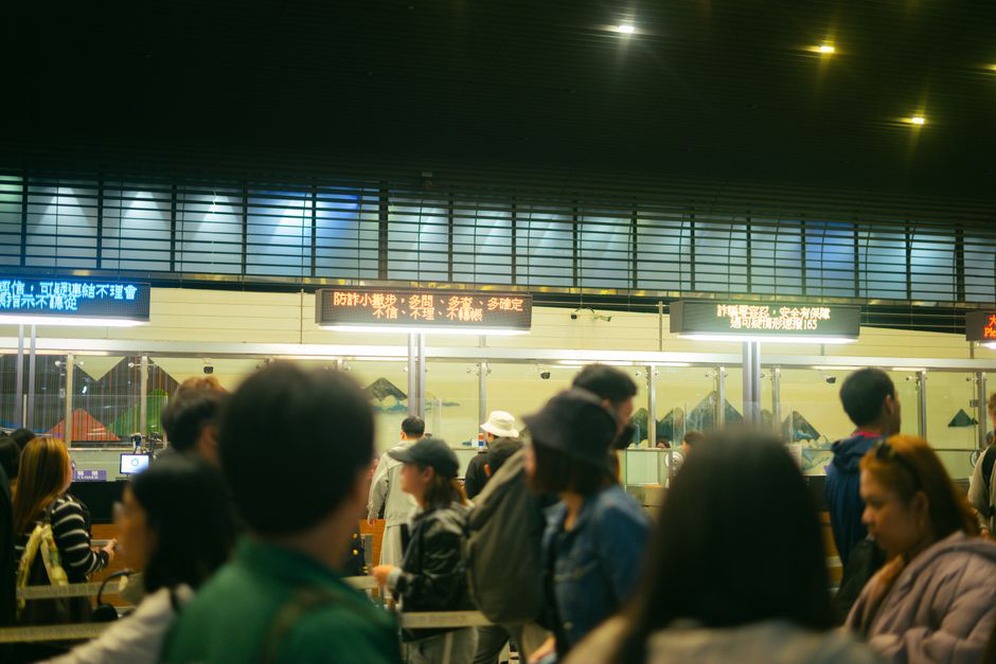
Reading the decade’s impact in its proper context
The enduring change was a greater emphasis on evaluating a biometric system, rather than a matching algorithm alone. Sensors, enrollment procedures, templates, search infrastructure, thresholds, human review, and error reporting all shaped outcomes. An improvement in one component could be lost elsewhere: a better face matcher could not recover detail absent from a tiny image, while a high-quality fingerprint capture could not correct an identity error made during enrollment.
A useful way to read a result from the period is to ask whether it measured verification or identification, whether subjects could be absent from the database, and whether failed captures counted. A reported 99% first-rank identification rate means one thing when every probe person is known to be enrolled and the images are clean. It means something else at a noisy checkpoint that must also reject people with no record. Those protocol details often tell you more than the headline percentage.