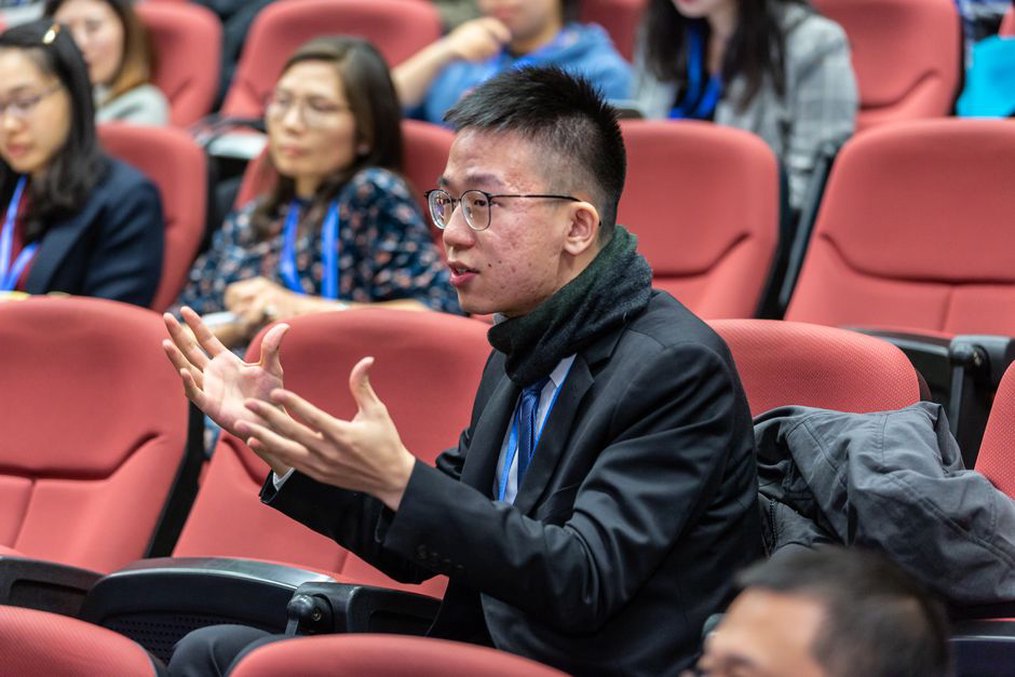
A tracker could follow a person through a short video sequence and still fail when that person passed behind an obstruction. At a 2000s computer-vision conference, its authors might also have to show what happened when the lighting changed or another person crossed the frame. The demand to demonstrate results before peers shaped the research itself. Conferences did more than report pattern-recognition methods: they affected which problems drew attention, what counted as evidence, and which comparisons researchers could make.
Why the conference format mattered
Pattern recognition in the 2000s covered speech, documents, medical images, biometrics, and computer vision. Researchers met at broad venues such as ICPR, specialized meetings such as CVPR, ICCV, and Interspeech, and regional conferences including PRASA in southern Africa. Their scopes differed, but each submitted paper had to make a compact, inspectable claim. Authors needed to define a task, explain a method, and show results within limited space.
That format favored work demonstrated on defined inputs and judged against a baseline. It also gave developing ideas a relatively quick route into public discussion. A paper might document a tracking failure, introduce a useful speech corpus, or report an unexpected recognition result before the research was settled. Proceedings captured active problems, not final verdicts on what worked.
Deadlines mattered too. They pushed teams to finish an experiment that others could inspect rather than keep adjusting a system indefinitely. Acceptance brought scrutiny, not a guarantee that the result would generalize. A strong score might depend on a particular dataset, feature representation, or training–test split—details a short paper could explore only so far.
Benchmarks gave researchers a common language
Without shared test material, two recognition systems could each claim improvement while solving slightly different problems. Conferences made comparisons more routine: papers named datasets, evaluation measures, and earlier methods readers could recognize. Organizers and associated workshops sometimes established common tasks; the papers showed how widely those tasks were used.
What a comparison made possible
Consider optical character recognition on scanned pages. An accuracy figure means little unless readers know whether the pages contain clean print, degraded type, handwriting, or mixed layouts. If authors test on the same collection using the same scoring rule, they can more readily ask whether a new segmentation stage helped, rather than wonder whether it was tested on easier pages.
Comparable results were especially useful for systems with several interacting parts. A 2000s speech recognizer might combine signal features, an acoustic model, a pronunciation dictionary, and a language model. A conference comparison could change one component while holding the rest roughly constant. Describing that design made the experiment useful even to readers who never adopted the proposed method.
Shared tests had a cost. Researchers could tune methods to familiar collections, and a high score on one benchmark did not establish performance with another accent, camera, scanner, or clinic. Improvement on a shared test was not the same as reliability elsewhere. As the same datasets appeared at successive meetings, that distinction became harder to ignore.
Short papers rewarded specific claims—and could hide complexity
A proceedings paper typically had far less room than a journal article for dataset construction, implementation choices, or negative results. Authors built their arguments around a few experiments. The constraint could sharpen a question: does an appearance model help a tracker recover after occlusion? Does a different feature set improve language identification from short speech clips?
It could also make results hard to reproduce. Preprocessing, parameter selection, and excluded samples might receive only brief treatment, even when they materially affected performance. When comparing two 2000s papers, a reader should look beyond the headline metric:
- Task definition: Were both systems detecting the same object, word, speaker, or document region?
- Test separation: Were training and test samples genuinely distinct under the paper’s stated protocol?
- Operating conditions: Did the results come from clean laboratory data or variable real-world recordings?
- Baseline: Was the comparison a credible earlier approach tested under similar conditions?
- Reported failures: Did the authors show where the method broke down, not just where it succeeded?
These are useful checks for a historian as well as a researcher. They help explain why a technique could attract conference attention yet prove difficult to put into a working system.
Workshops brought neglected problems into view
Large conferences often organized attention around established research tracks. Workshops and regional meetings made room for problems that lacked a familiar benchmark or the resources of a large laboratory. That mattered for under-resourced languages, locally collected data, and applications shaped by particular institutions.
In southern African speech research, for example, a new annotated corpus, pronunciation resource, or evaluation design for languages with limited training data could be a substantial contribution, even without a leading recognition score at a broad international meeting. PRASA proceedings show researchers treating these resource questions as technical problems, not merely missing inputs. Later work described in the blog’s analysis of a 2012 PRASA paper on under-resourced language research illustrates how much one proceedings paper can reveal about the practical constraints behind a system.
Workshops also brought neighboring communities together around a problem rather than a single method. Someone building a language identifier could draw on speech recognition, statistical classification, and corpus design. A medical-image researcher might borrow an image-segmentation idea while needing a very different standard for acceptable error. Meeting across fields did not mean their evaluation rules were interchangeable.
Demonstrations and discussion exposed different failures
Tables recorded measured outcomes; a demonstration or poster conversation could reveal the behavior behind them. In visual tracking, an image sequence might show whether a system kept the right identity after two objects crossed. In document analysis, examples might reveal trouble with tables or unusual page layouts hidden by a strong average score. Informal observation did not replace testing, but it could suggest the next test.
Peer questions pushed authors to state a result’s limits. Was a face-recognition method evaluated across different capture conditions? Did a stereo-vision system require careful camera calibration? Were speakers in the test recordings also represented in training? Such questions tied experimental design to intended use. The proceedings did not preserve every exchange, so a specific change cannot be credited to conference discussion without a record. Presenting work nonetheless made its assumptions available for immediate challenge.
Proceedings reveal influence without proving a straight line
Conference archives help historians trace when a term, dataset, or evaluation practice appeared in print and how authors positioned their work. Repeated citations may show that a paper became a reference point. They do not prove that a conference invented a technique or caused its adoption. Ideas also moved through journals, laboratories, software, shared data, and conversations outside published sessions.
The archive has other gaps. It records accepted submissions more clearly than abandoned approaches or systems that missed a deadline. Even among accepted papers, an apparent trend may reflect a popular benchmark rather than a change in the underlying application. Reading across several years and venues helps distinguish a sustained research problem from a brief burst of submissions.
A useful place to start is with two papers reporting the same kind of result, such as tracking accuracy. Read their evaluation sections side by side: if one tests uninterrupted footage and the other includes occlusion and re-entry, their scores answer different questions. The telling details are the test sequence each names, the baseline it uses, and the failures its authors choose to show.